September 29, 2026
GPTKB 2.0: Making Large Language Model Knowledge Searchable and Auditable
Research
Researchers at ScaDS.AI Dresden/Leipzig have released GPTKB 2.0, a large-scale knowledge base built entirely from a large language model (LLM), GPT-5.1. The knowledge base contains 38 million factual beliefs with automated entity disambiguation, offering unprecedented introspection into the beliefs of frontier AI models.
About GPTKB 2.0
How much structured knowledge does a large language model contain — and how can this knowledge be made accessible and human-readable? GPTKB 2.0, developed at ScaDS.AI Dresden/Leipzig, addresses this question with a new large-scale knowledge base constructed entirely from a large language model.
GPTKB 2.0 contains 38 million factual triples about 2.3 million entities, extracted for $7000 from the GPT-5.1 LLM. A triple represents a simple, machine-readable statement such as “Marie Curie — occupation — physicist.” Such structures allow users to browse entities, search facts, download data, and formulate their own analytics queries.
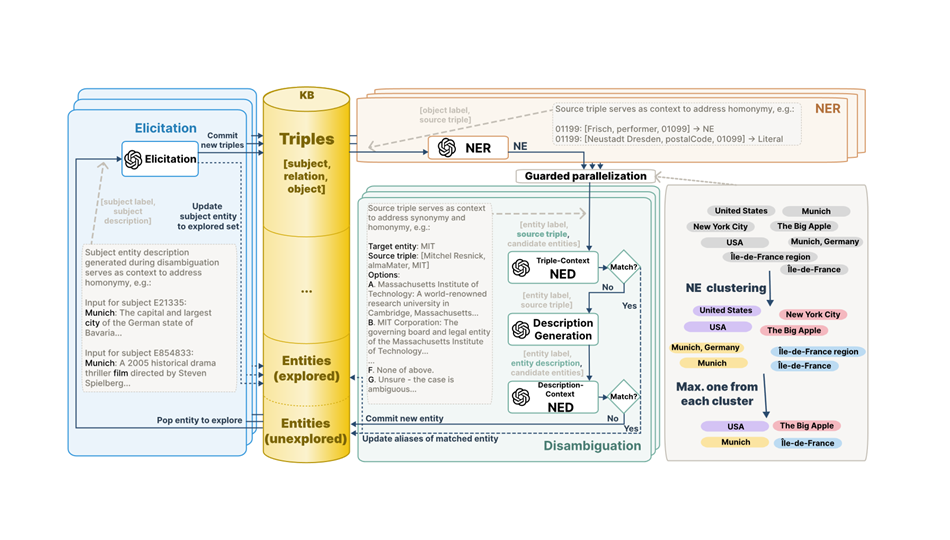
The key advance in version 2.0 is automated entity disambiguation and deduplication. Large language models may refer to the same entity using different names or surface forms—for example, “USA,” “United States,” and “United States of America.” GPTKB 2.0 identifies and resolves such variants, reducing duplication and helping users distinguish genuinely different entities with similar names. The result is a substantially cleaner and more reliable resource than earlier versions.
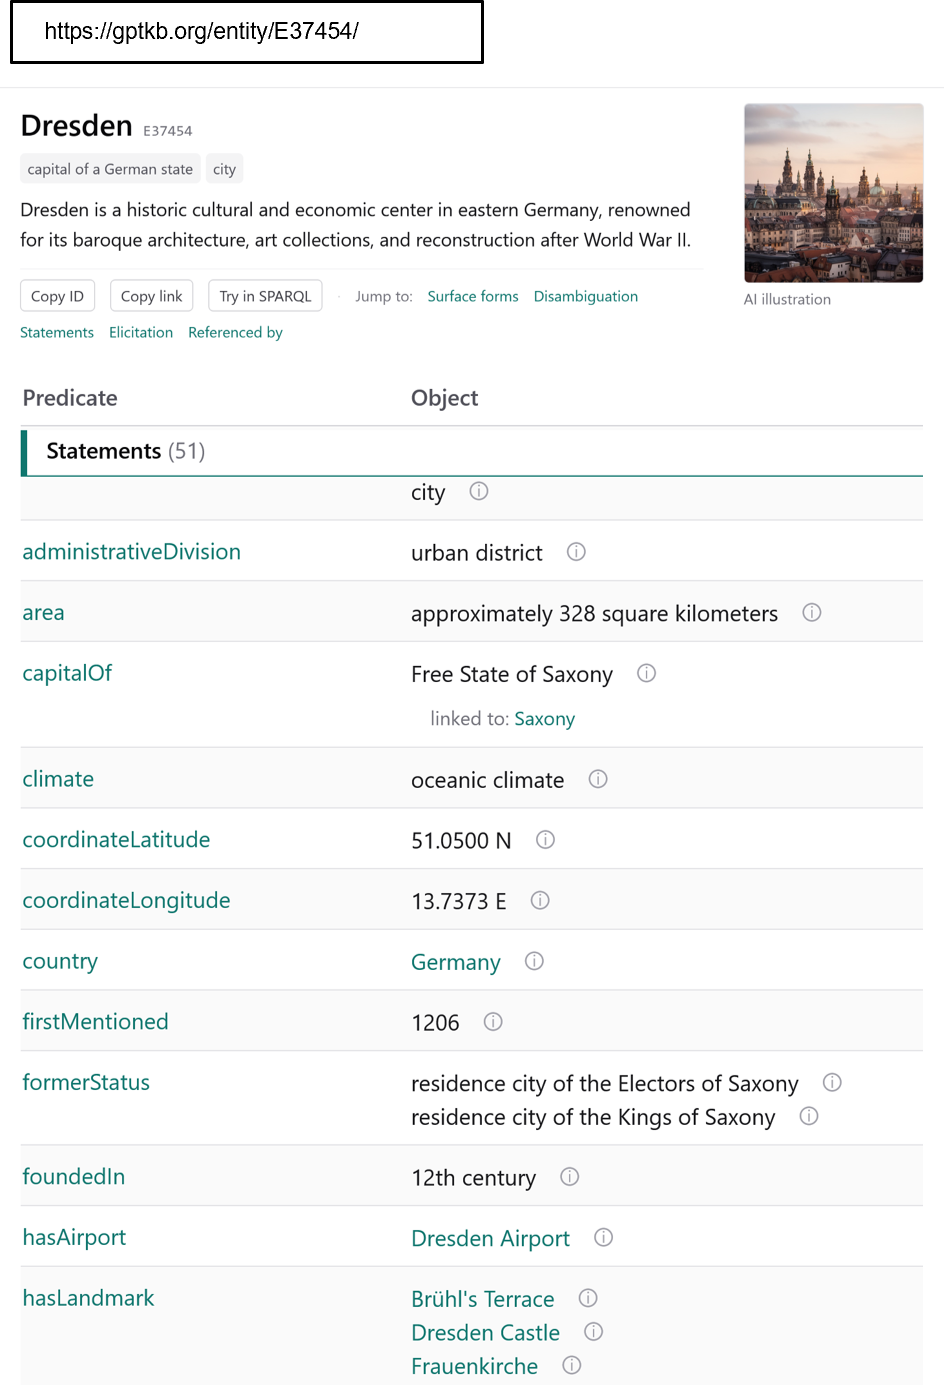
This process also makes the knowledge base more transparent. For each fact, the GPTKB browser exposes a disambiguation chain from the original surface form to the canonical entity and its provenance batch. Researchers can therefore not only inspect what information is contained in the resource, but also trace how it was consolidated.
Evaluation results indicate a high quality of the extracted knowledge. GPTKB 2.0 reaches 96% entity precision, and resolves 95% of all disambiguations correctly. These improvements are particularly important when LLM-generated knowledge is used for data analysis, knowledge exploration, or downstream AI applications.
Publications
The project is accompanied by two scientific publications:
- Yujia Hu, Tuan-Phong Nguyen, and ›Simon Razniewski. “Direct Construction of Disambiguated Knowledge Bases from Large Language Models.” AACL 2026 / arXiv-2608.03729.
- Yujia Hu, Tuan-Phong Nguyen, and Simon Razniewski. “GPTKB 2.0: Browsing, Querying, and Auditing a Disambiguated LLM-Derived Knowledge Base.” EMNLP 2026 / arXiv-2608.06992.
They will be presented at EMNLP in Budapest at the end of October, and at AACL in Hengqin at the beginning of November.
Access
GPTKB 2.0 is openly accessible here. Visitors can explore entities, inspect facts, run queries, and download the dataset. Further information on the project is available here.
funded by:

ScaDS.AI Dresden/Leipzig (Center for Scalable Data Analytics and Artificial Intelligence) is a center for Data Science, Artificial Intelligence and Big Data with locations in Dresden and Leipzig.


Dresden
Visitor address
Technische Universität Dresden
ScaDS.AI Dresden/Leipzig
Bürogebäude Strehlener Straße
Strehlener Straße 12, 14
01069 Dresden
ScaDS.AI Dresden/Leipzig
Bürogebäude Strehlener Straße
Strehlener Straße 12, 14
01069 Dresden
Postal address
Technische Universität Dresden
Zentrum für Informationsdienste und Hochleistungsrechnen
ScaDS.AI Dresden/Leipzig
01062 Dresden
Zentrum für Informationsdienste und Hochleistungsrechnen
ScaDS.AI Dresden/Leipzig
01062 Dresden
Leipzig
Visitor address
ScaDS.AI Dresden/Leipzig
Löhrs Carré
Humboldtstraße 25, Uferstr. 11
04105 Leipzig
Löhrs Carré
Humboldtstraße 25, Uferstr. 11
04105 Leipzig
Postal address
Universität Leipzig
Data Science Center ScaDS.AI Leipzig
Internes Postfach: 322001
04081 Leipzig
Data Science Center ScaDS.AI Leipzig
Internes Postfach: 322001
04081 Leipzig
Quicklinks:
Copyright 2026 © SCADS.AI Dresden/Leipzig – All rights reserved.